
Fine-tuning a model using SFT
1
Confirm model support for training
You can confirm that a base model is available to train by looking for the And looking for
Tunable tag in the model library or by using:Tunable: true.Custom uploaded base models must include a corresponding Hugging Face URL before Fireworks can determine whether they are tunable. Fireworks uses the URL to infer the training renderer and find compatible training shapes. The tunability refresh runs asynchronously about every 30 minutes, so a newly uploaded or updated custom model may take up to 30 minutes to show
Tunable: true.Some base models cannot be tuned on Fireworks (
Tunable: false) but still list support for LoRA (Supports Lora: true). This means that users can tune a LoRA for this base model on a separate platform and upload it to Fireworks for inference. Consult importing trained models for more information.2
Prepare a dataset
A dataset is JSONL: one JSON object per line, from 3 to 3 million lines. Each object has a
messages array and may have a tools array of OpenAI function definitions. There is no weight on the example itself.Each message is an object:role:system,user,assistant, ortoolcontent: a string, or a list of parts. A text part is{"type": "text", "text": "..."}. A thinking part is{"type": "thinking", "thinking": "..."}. One text part is the same as a string. Several parts stay separate through the chat template. Image parts are under Vision training.tool_calls: optional on an assistant message, and enough on its own whencontentis omitted. Use{"type": "function", "function": {"name": "...", "arguments": ...}}, whereargumentsis a JSON object or a JSON string.{"name": "...", "args": {...}}is also accepted.weight: optional number on a message.0excludes that message from the loss. Any other number trains it.trainableis a boolean for the same switch and wins when both are set.
tool message returns a tool result and should set tool_call_id. Assistant thinking can also be a string field, thinking, reasoning, or reasoning_content. When more than one is set, thinking is used, then a non-empty reasoning, then a non-empty reasoning_content. Whether earlier thinking remains in later turns depends on the base model.Thinking history in training
Compare every supported model, understand per-user-turn unrolling, configure the job field, and preview what the trainer will see.
3
Upload a dataset
Upload the dataset with the Fireworks UI, While all of the above approaches should work,
firectl, or the REST API.- UI
- firectl
- Restful API
-
You can simply navigate to the dataset tab, click
Create Datasetand follow the wizard.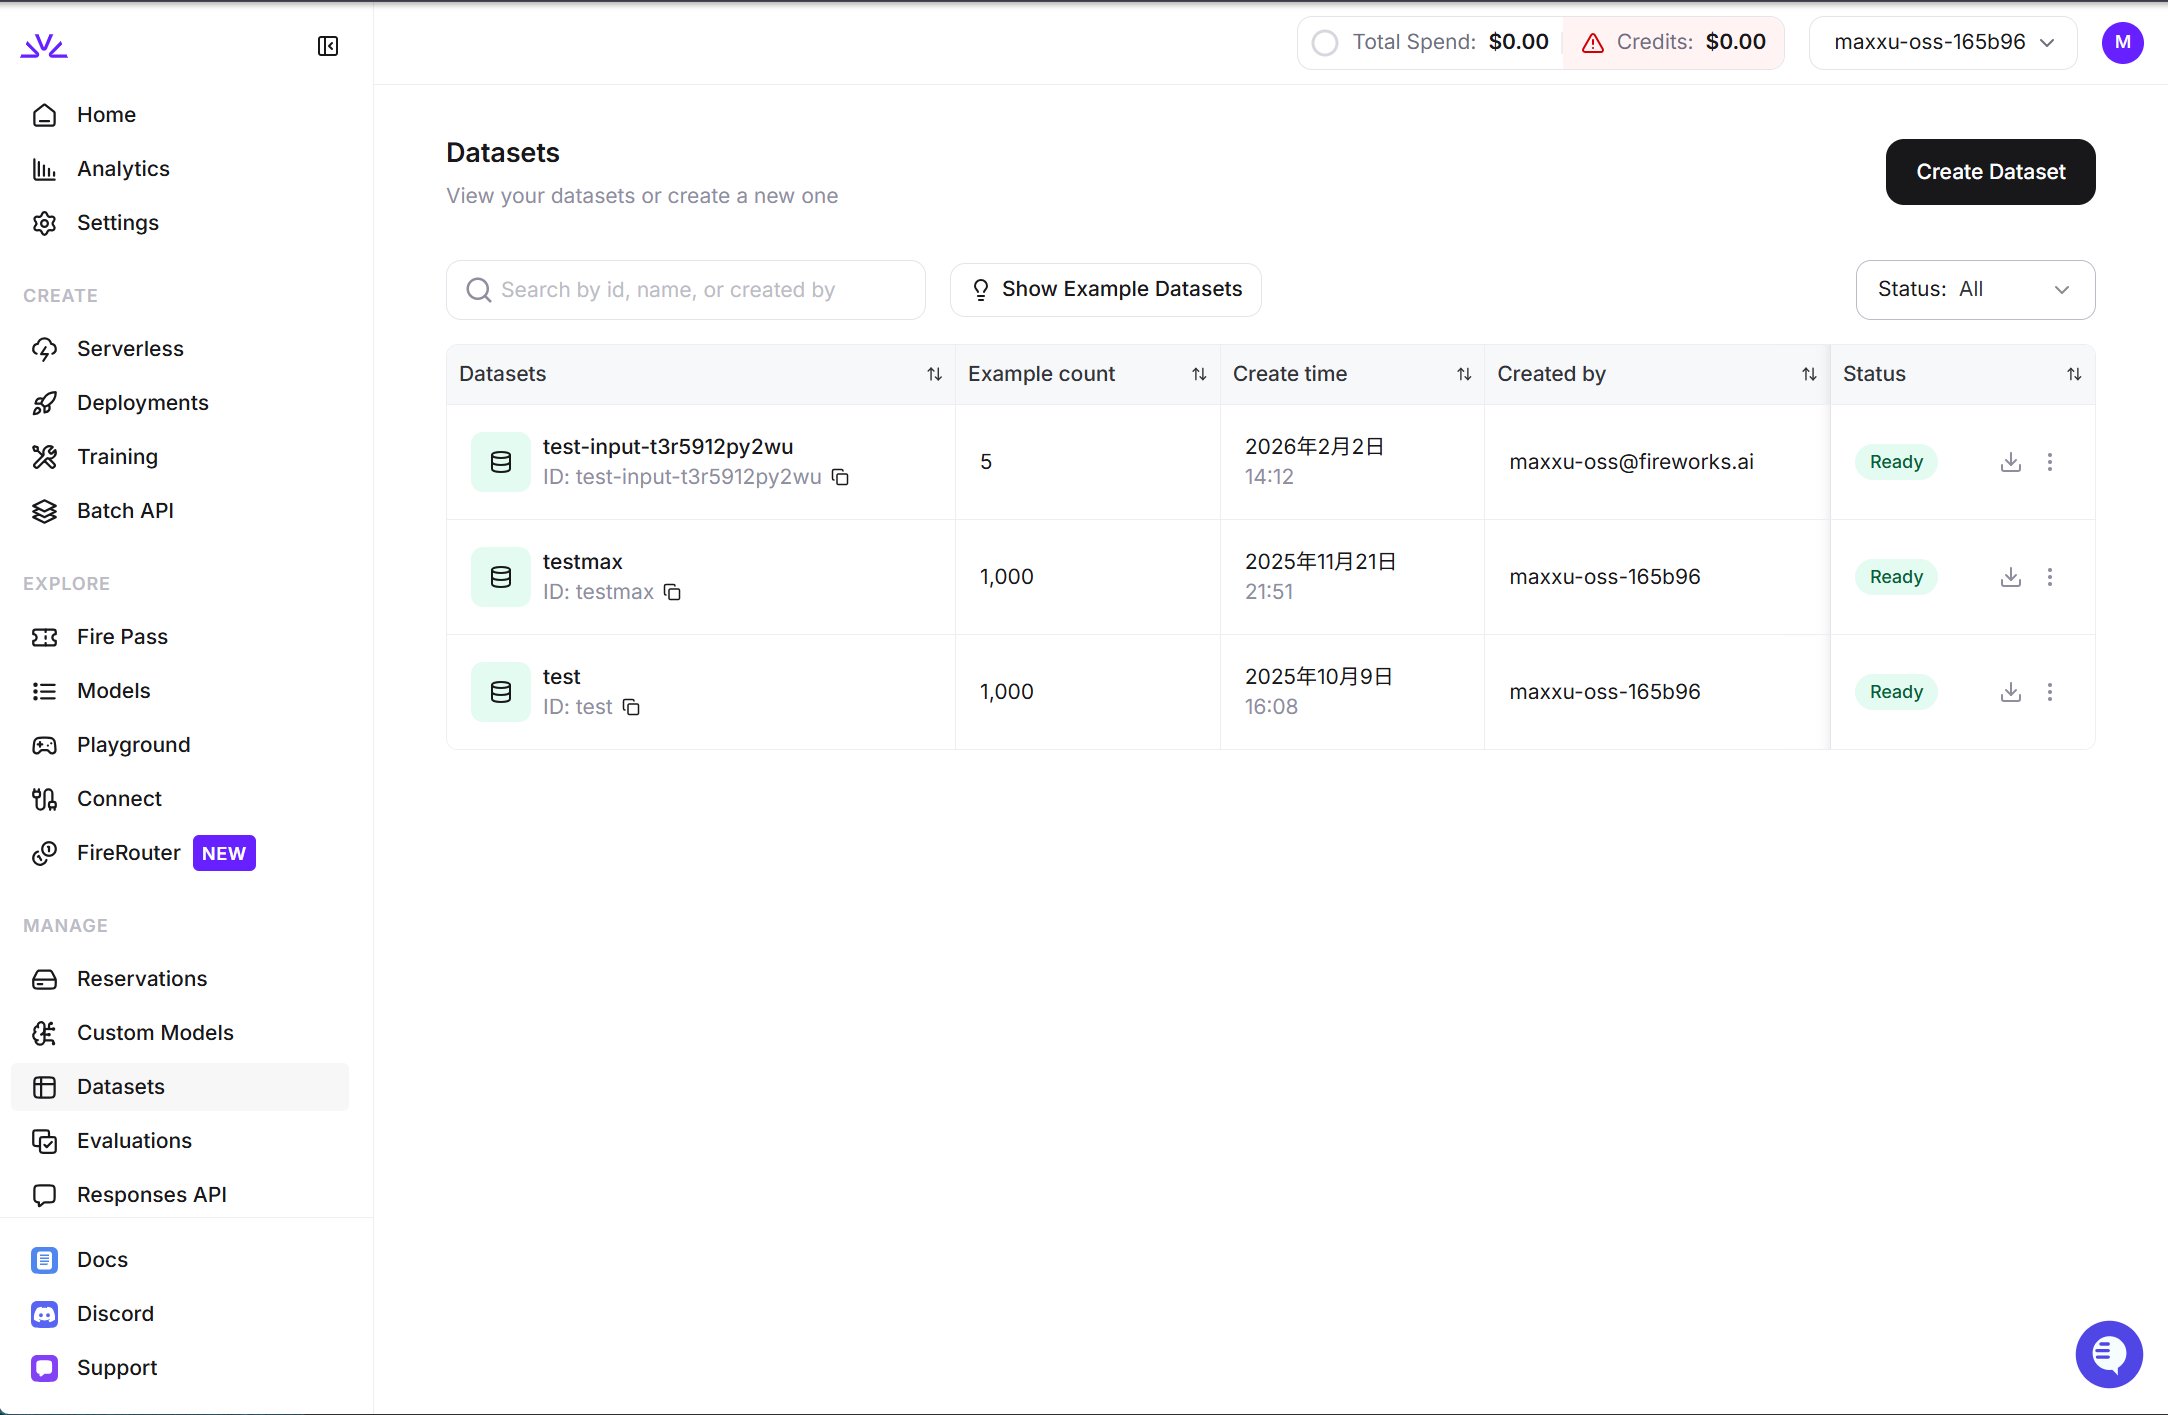
UI is more suitable for smaller datasets < 500MB while firectl might work better for bigger datasets.Ensure the dataset ID conforms to the resource id restrictions.4
Launch a training job
There are also a couple ways to launch the training jobs. We highly recommend creating supervised fine-tuning jobs via With 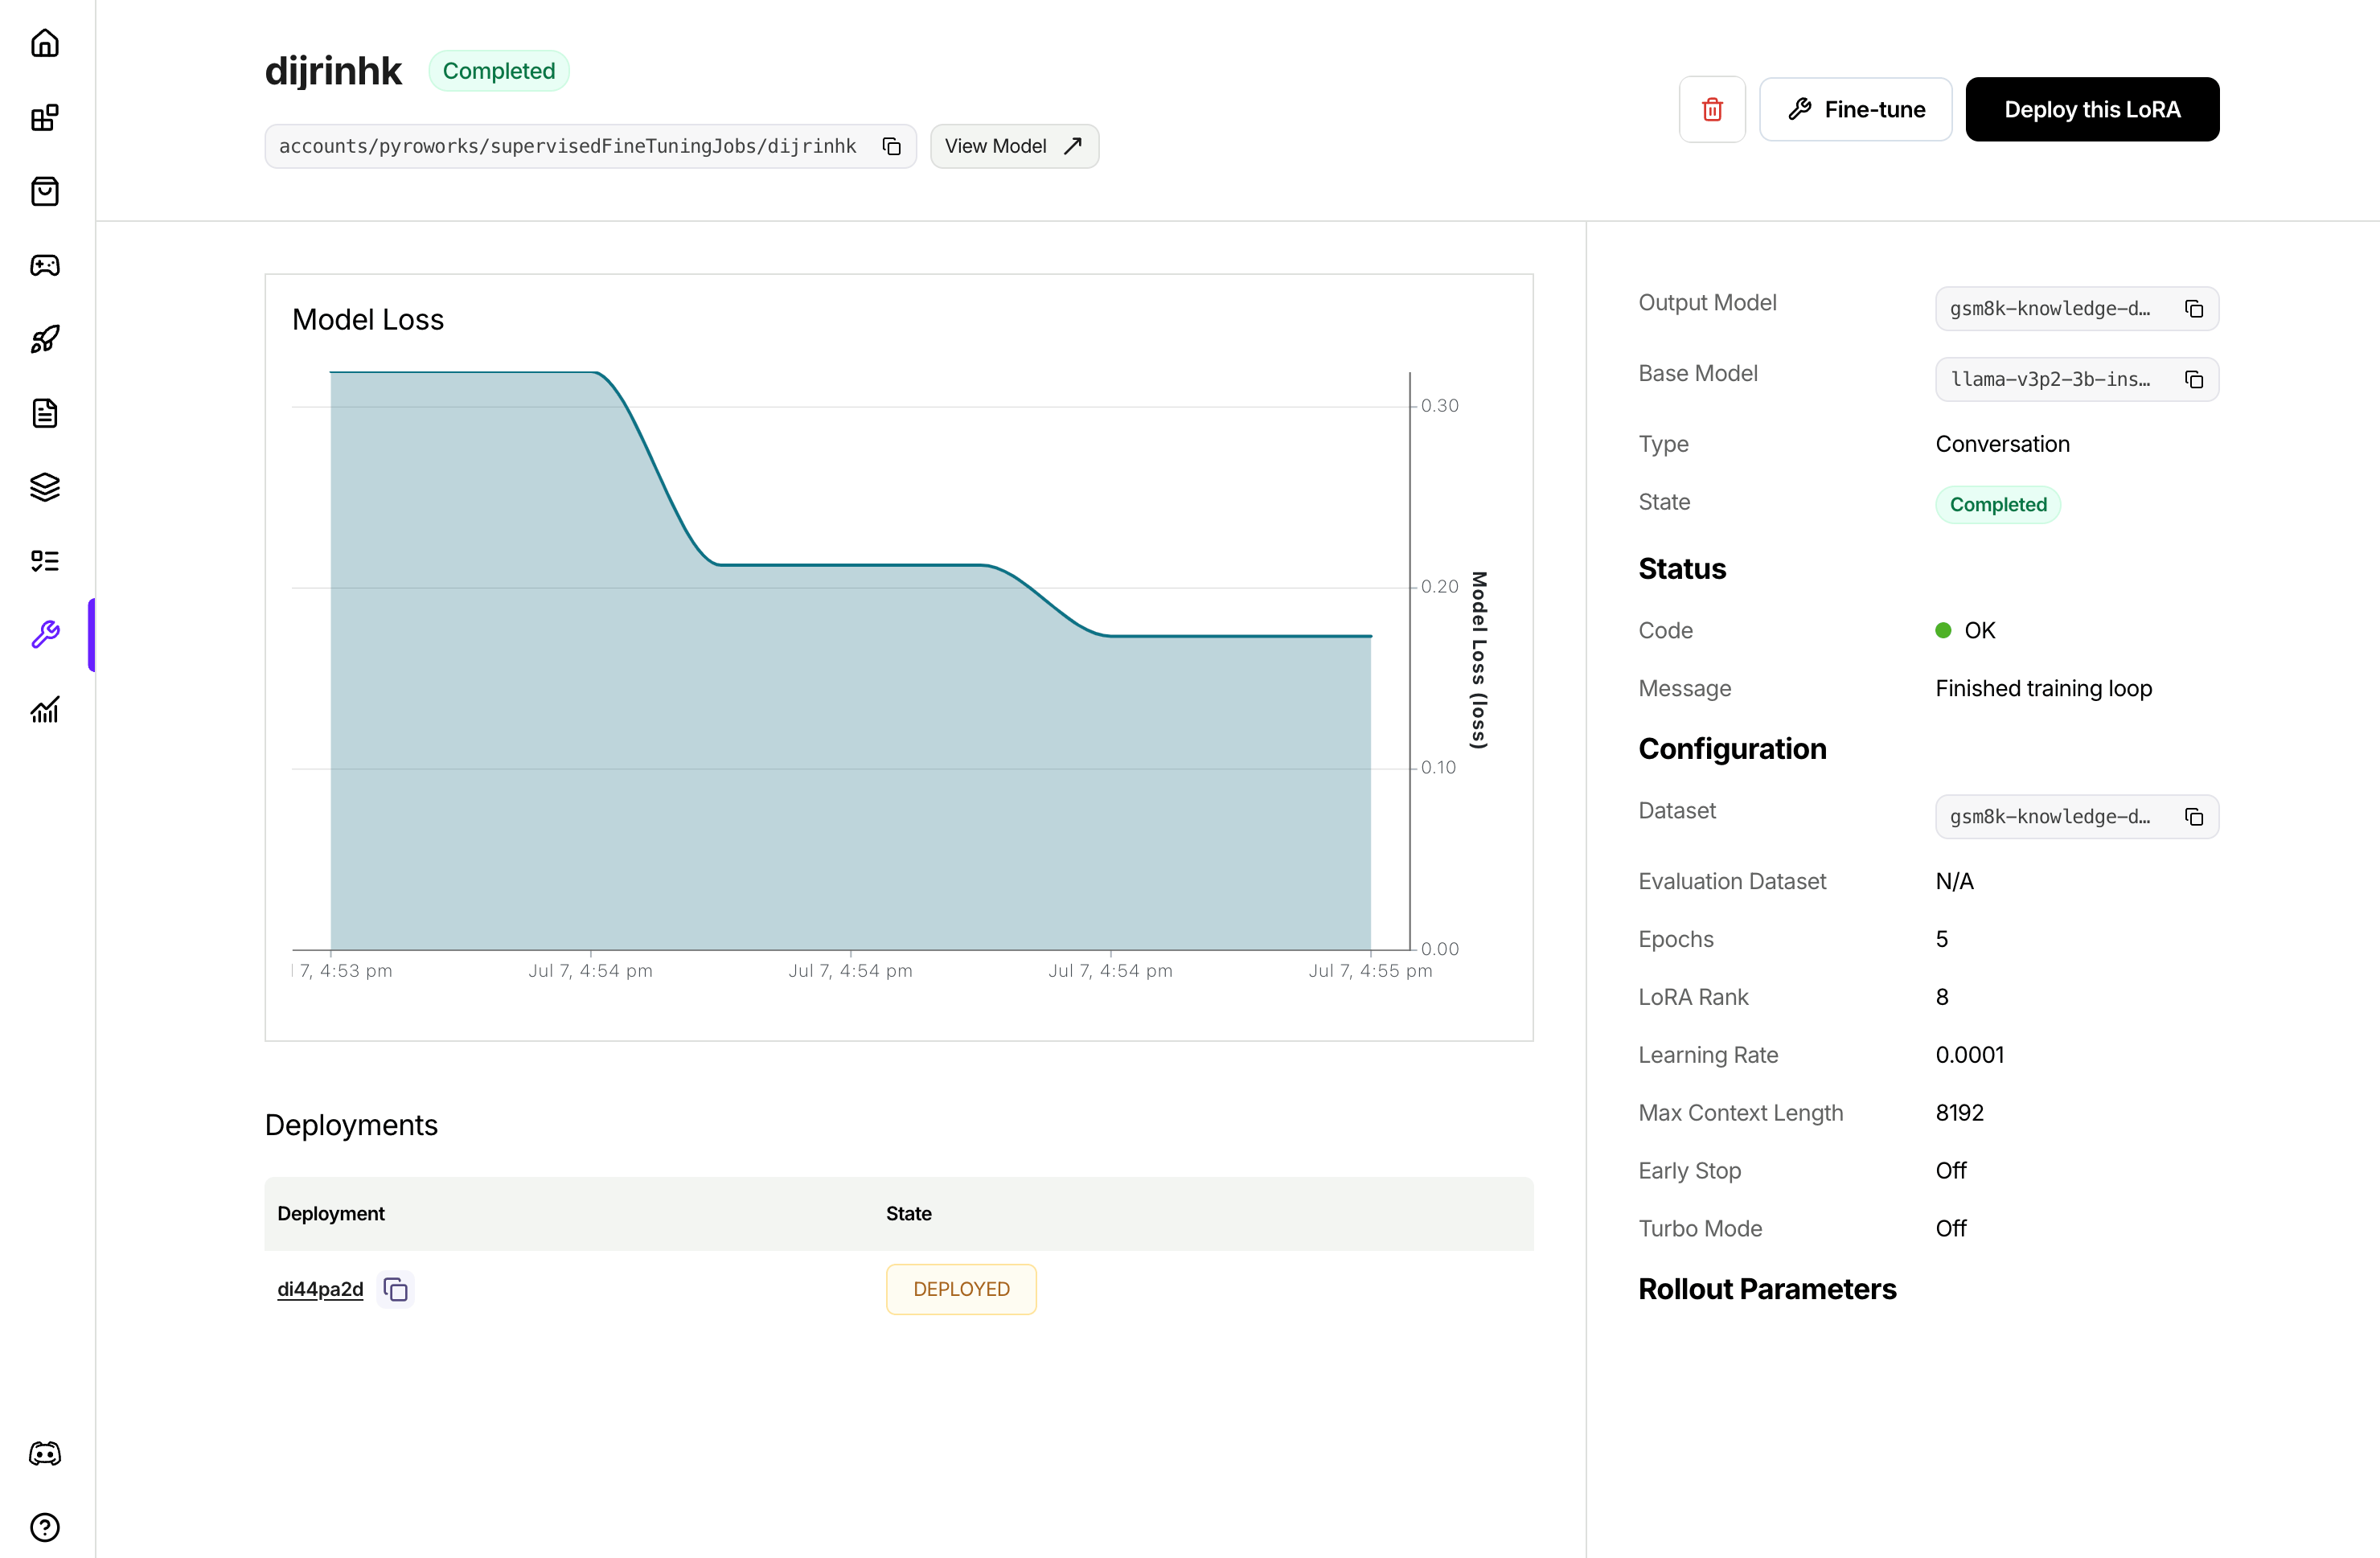
UI .- UI
- firectl
Simply navigate to the 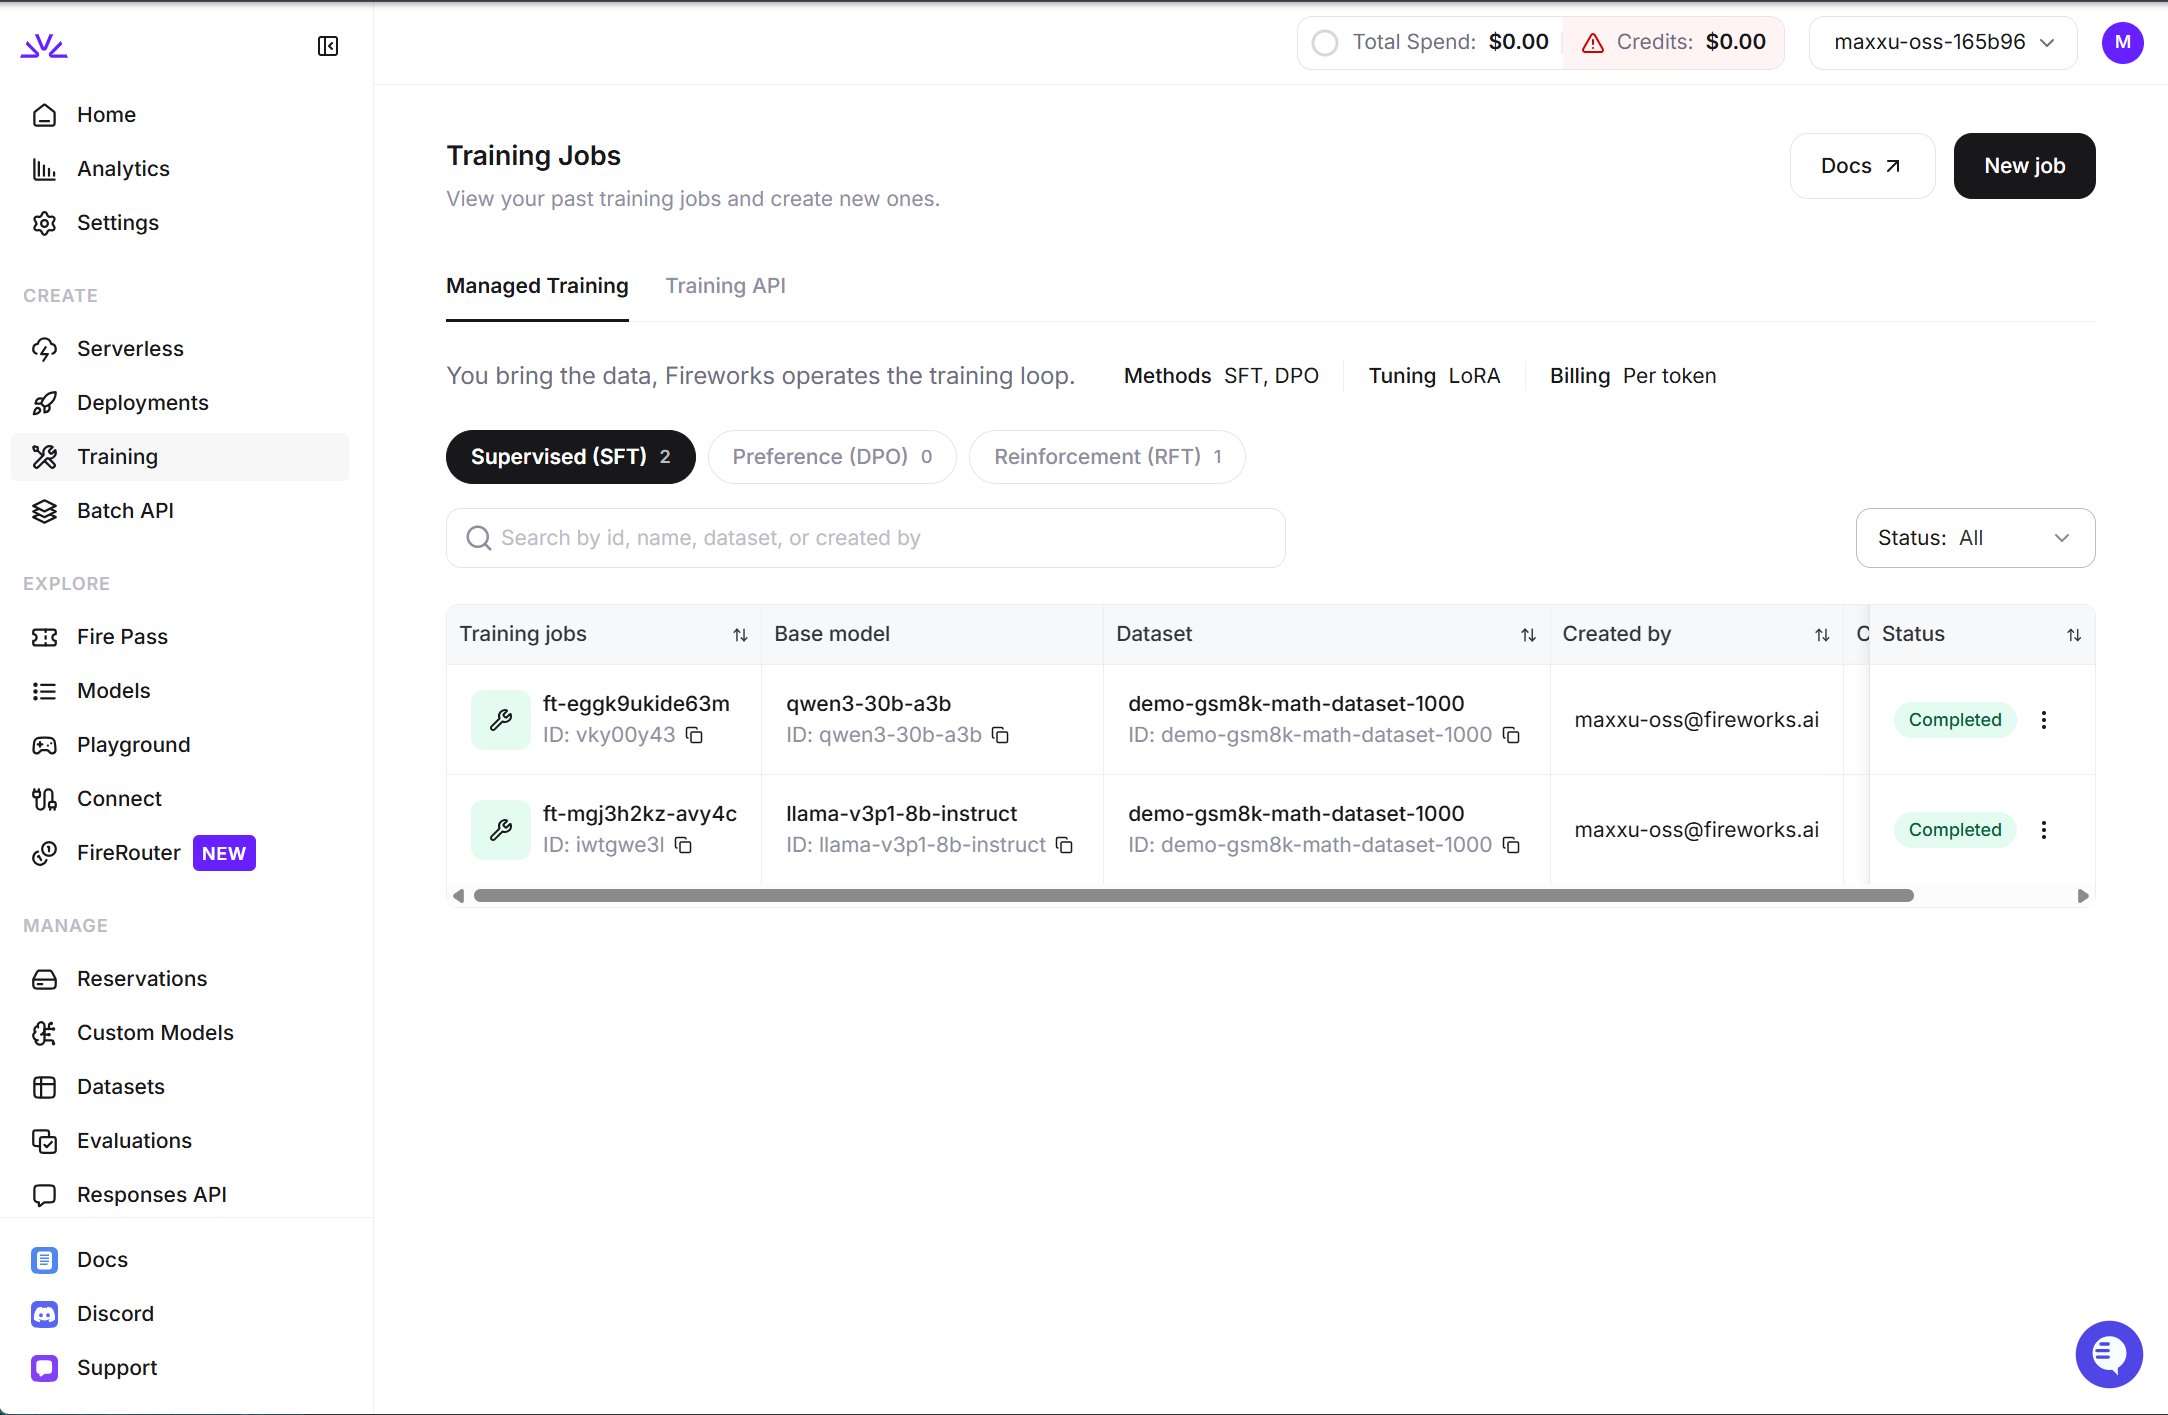
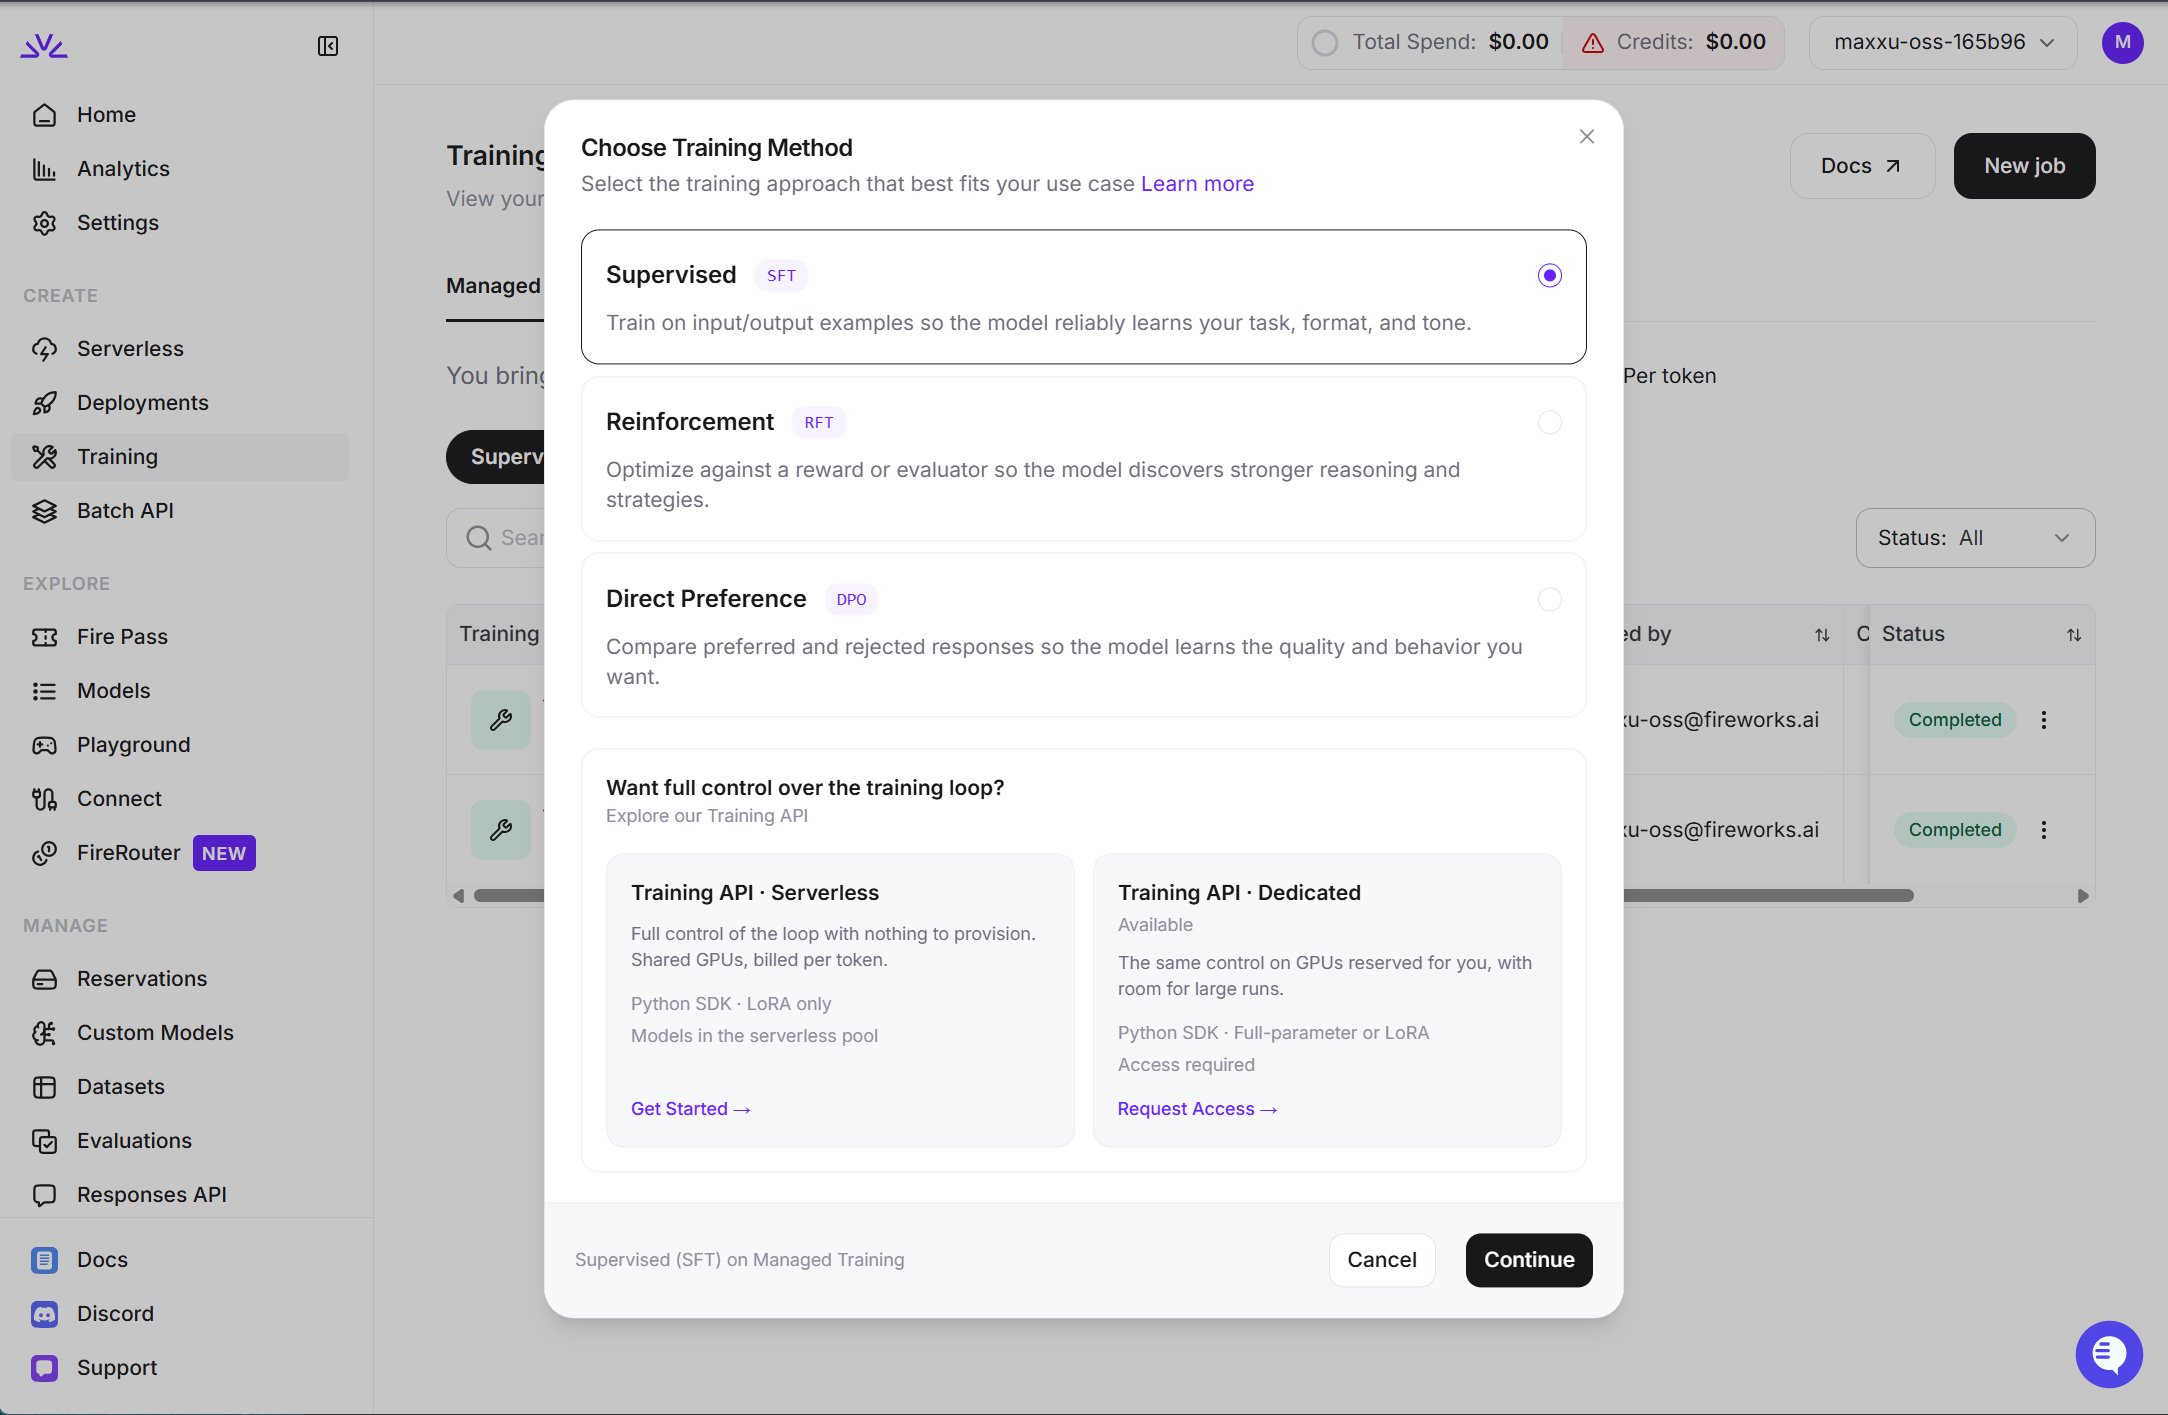
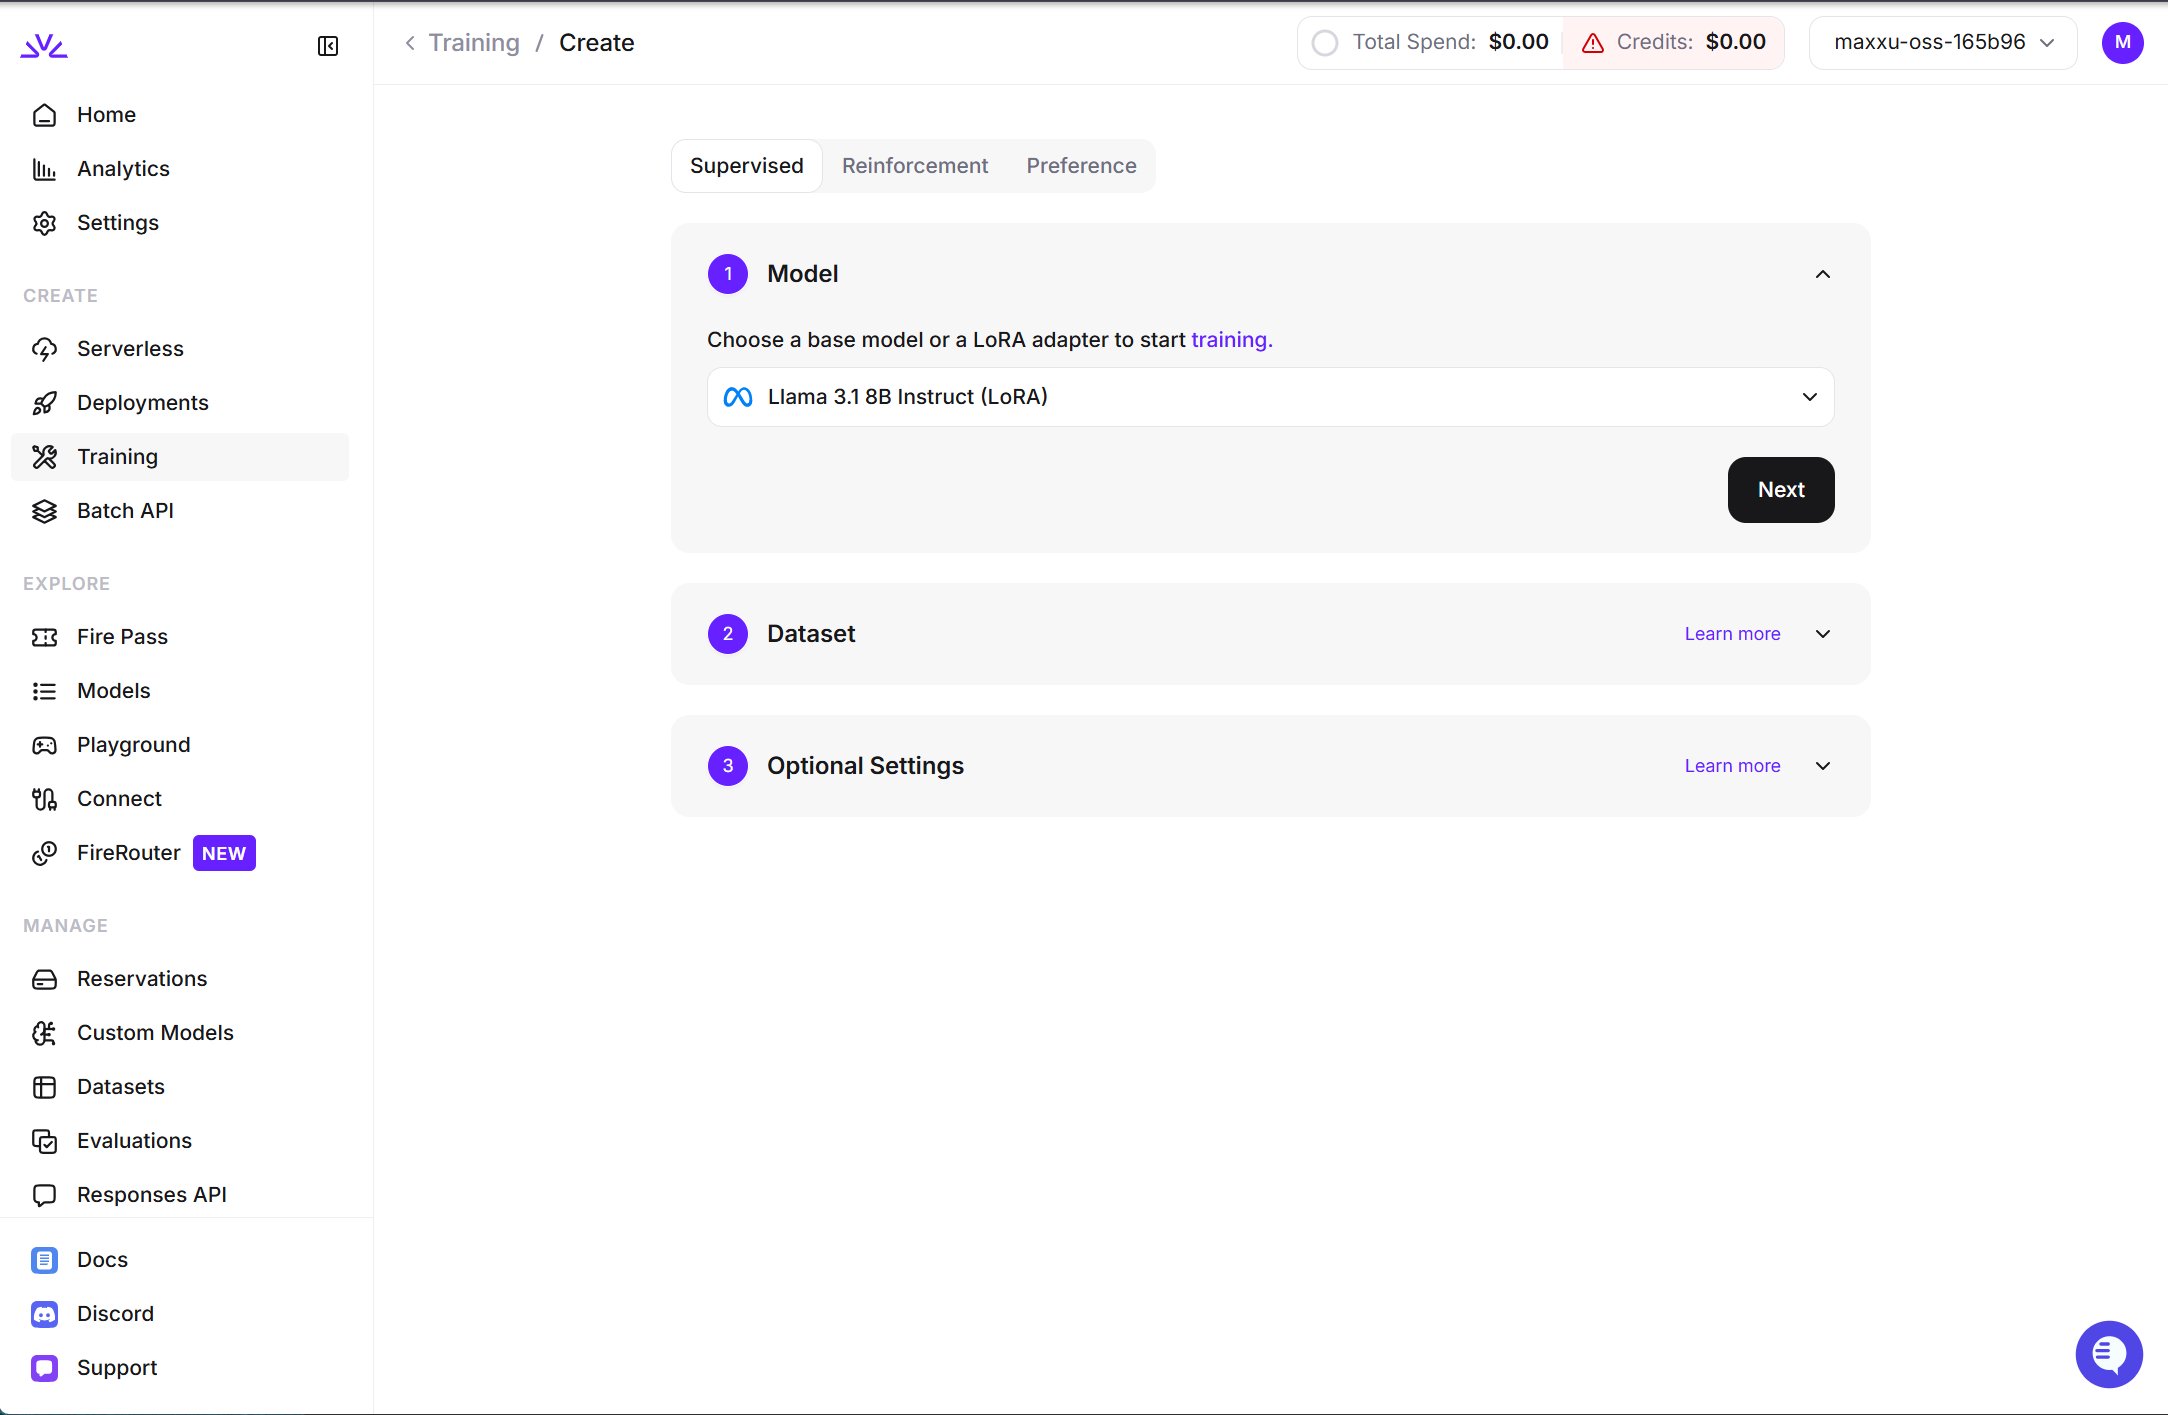
Training tab, click New job and follow the wizard from there. You can even pick a LoRA model to start the training for continued training.UI, once the job is created, it will show in the list of jobs. Clicking to view the job details to monitor the job progress.firectl, you can monitor the progress of the tuning job by runningDeploying a trained model
After training completes, evaluate the model before you hold dedicated capacity for production serving. To deploy for inference:default, see Deployment shapes.
Additional managed training job settings
Additional tuning settings are available when starting an SFT or preference (DPO/ORPO) job. All of the settings below are optional and have reasonable defaults. For settings that affect tuning quality, such asepochs and learning_rate, use the defaults first and change them only when the results indicate a clear need. Examples use SFT unless otherwise noted.
Evaluation
Evaluation
By default, the training job will run evaluation by running the trained model against an evaluation set that’s created by automatically carving out a portion of your training set. You have the option to explicitly specify a separate evaluation dataset to use instead of carving out training data.
evaluation_dataset: The ID of a separate dataset to use for evaluation. Must be pre-uploaded via firectlMax Context Length
Max Context Length
Depending on the size of the model, the default context size will be different. For most models, the default context size is >= 32768. Training examples will be cut-off at 32768 tokens. Usually you do not need to set the max context length unless out of memory error is encountered with higher lora rank and large max context length.
Batch Size (Samples)
Batch Size (Samples)
Managed SFT and preference tuning use sample-count batching.
batch_size_samples is the number of SFT samples or preference pairs included in each optimizer step. It is independent of max_context_length, which limits the token length of each sample. The UI defaults are 32 samples for SFT and 4 preference pairs for DPO/ORPO.Epochs
Epochs
Epochs are the number of passes over the training data. Our default value is 1. If the model does not follow the training data as much as expected, increase the number of epochs by 1 or 2. Epochs must be a whole number.Note: we set a max value of 3 million dataset examples × epochs
Learning rate
Learning rate
Learning rate controls how fast the model updates from data. We generally do not recommend changing learning rate. The default value is automatically based on your selected model.
Learning rate warmup steps
Learning rate warmup steps
Learning rate warmup steps controls the number of training steps during which the learning rate will be linearly ramped up to the set learning rate.
Learning rate scheduler
Learning rate scheduler
Configure how the learning rate changes over training. Supported schedulers are Via the REST API, pass an
constant, linear, and cosine. When unset, the trainer uses its legacy constant schedule. The same flags apply to SFT and preference tuning jobs (DPO/ORPO).For linear and cosine, you can optionally set:--learning-rate-min-lr-ratio: minimum learning rate as a fraction of--learning-rate(0 to 1)--learning-rate-decay-ratio: fraction of total training steps over which to decay;0decays over the full run
lrScheduler object with one of constant, linear, or cosine:LoRA Rank
LoRA Rank
LoRA rank refers to the number of parameters that will be tuned in your LoRA add-on. Higher LoRA rank increases the amount of information that can be captured while tuning. The maximum rank depends on the base model’s training shape, up to 128; higher values are rejected.
firectl defaults to 8.With the REST API or the Python SDK, always set the rank to train a LoRA adapter: loraRank in the job body, or lora_rank in supervised_fine_tuning_jobs.create(...). An omitted rank is sent as 0, which requests full-parameter training.Training progress and monitoring
Training progress and monitoring
The training service integrates with Weights & Biases to provide observability into the tuning process. To use this feature, you must have a Weights & Biases account and have provisioned an API key.
Model ID
Model ID
By default, the training job will generate a random unique ID for the model. This ID is used to refer to the model at inference time. You can optionally specify a custom ID, within ID constraints.
Job ID
Job ID
By default, the training job will generate a random unique ID for the training job. You can optionally choose a custom ID.
Reservation placement
Reservation placement
Reservation placement is off unless you request it. If you request it and your account has an active reservation for the job’s accelerator type, the job runs only on that reservation, not on shared trainer capacity. If the account has no matching reservation, the setting is ignored and the job uses shared capacity.
- firectl: add
--use-reservation. - REST: set
useReservation: truein the job body. - Python SDK: pass
use_reservation=Truetosupervised_fine_tuning_jobs.create(...).
Deprecated parameters
Appendix
Python SDKreferencesRestful APIreferencesfirectlreferences- Complete Python SDK workflow example for a code-only implementation
Vision training
Vision SFT uses the samemessages JSONL. Put image parts on user messages. Some vision renderers also allow them on tool messages. system and assistant messages cannot contain images. Encode each image as a data:image/<type>;base64,... URI before upload, and keep the MIME type accurate (image/jpeg, image/png).
These parts are the same image:
{"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,..."}}{"type": "image_url", "image_url": "data:image/jpeg;base64,..."}{"type": "image", "image": "data:image/jpeg;base64,..."}
Debug SFT tokenization
If the model learns the wrong text or ignores assistant turns, the training renderer may not match inference tokenization.- In the dashboard, open your SFT job → Render Samples to inspect token boundaries and loss masks.
- Compare rendered tokens against inference for the same prompt.
- For custom renderers or agent-driven debugging, use the training skill — renderer verification.
In the REST response, the render preview identifies each datum produced from a source row with
examples[].renderings[].renderedDatums[].datumIndex. Downloaded Render Samples use the legacy split_index field. The fields play corresponding roles in different schemas; split_index has not been renamed in the downloadable artifact.